





Table of contents
Data masking vs encryption: how each one protects sensitive data, when to use which, and why most enterprises need both.
Table of Contents
How masking differs from encryption and when to use each
Data masking at a glance
Data encryption at a glance
Types of Data Masking
Types of Data Encryption
Data Masking vs Encryption: 2 Key Differences
Data Masking Use Cases
Data Encryption Use Cases
With a Data Product Platform, You Don’t Have to Choose
Key takeaways
-
Data masking replaces sensitive values with realistic fake values that can't be reversed, so the data stays usable for testing and analytics
-
Encryption turns data into ciphertext that anyone with the right key can decrypt
-
Masking fits non-production environments, while encryption fits data at rest and in transit
-
Most enterprises use both, and add tokenization where they need to recover the original value
-
A business entity approach lets one platform mask, encrypt, and tokenize sensitive data
Should you use data masking or encryption?
Data privacy and governance teams choosing a data protection approach usually ask the same two questions. Which is better for a given repository, data masking or encryption? And does the business need both?
The two methods share some traits, but they protect data in different ways. Knowing how each one works helps you pick the right protection for sensitive data and stay compliant with laws like GDPR, CCPA, and DORA.
Most enterprises end up using both. In our 2026 State of Enterprise Data Compliance survey, 87% of respondents said they use encryption, and 79% use static masking or anonymization.
In this article, we compare data masking and encryption, explain when to use each, and show how a business entity approach lets you apply both without trade-offs.
How does data masking protect sensitive data?
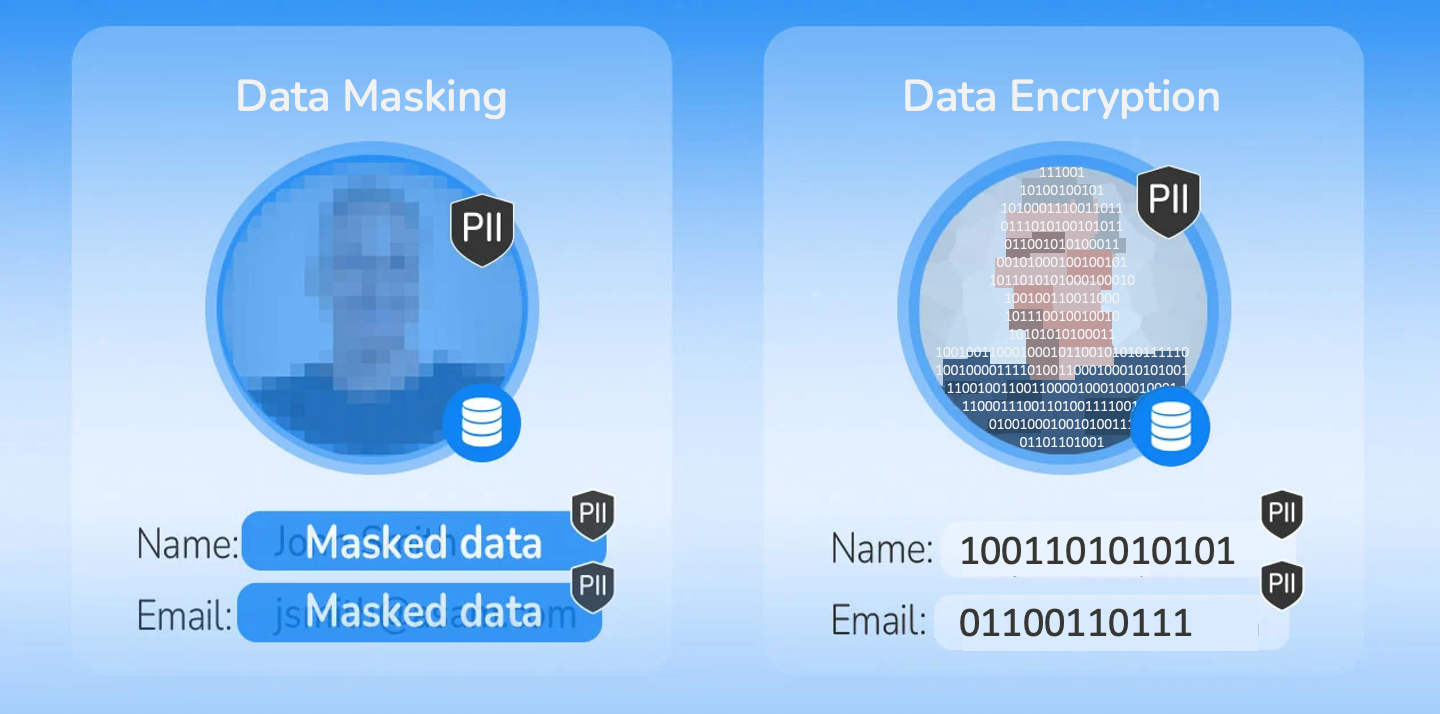
Data masking replaces real, sensitive data with fictitious but realistic values. Masked data can’t be traced back to the original or reversed. But it keeps its format and relationships, so teams can still use it for software testing and data science.
Masking can be static, dynamic, or in-flight. Good data masking tools keep referential integrity across databases and analytics platforms.How does data encryption protect sensitive data?
Encryption converts readable plaintext into unreadable ciphertext. It uses a mathematical algorithm and a cryptographic key to do it.
Unlike masking, encryption is reversible. Anyone with the right key can decrypt the data and see the original values. That makes the key the weak point. If attackers get it through hacking or social engineering, they can read the data.
What are the main types of data masking?
- Static data masking
Static data masking techniques are most commonly used to anonymize sensitive data on a backup of a production database, or a “dummy” database. They alter data while maintaining referential and contextual integrity, for use in development, testing, and training. - Dynamic data masking
Dynamic data masking transforms sensitive data in real time, to enable role-based security. When a user queries data, the data streams from a database or production environment are masked on-the-fly, depending on roles and permissions. - In-flight data masking
In-flight masking protects data as it moves from production to a target environment, such as test or analytics. Because nothing is staged in the clear along the way, PII is never exposed at rest.
What are the main types of data encryption?
-
Symmetric encryption
Also known as private key encryption, symmetric encryption relies on the same key to both encode and decode encrypted data. This type of encryption is best suited for individual users and closed systems. The main risk associated with symmetric encryption is the interception of the key by an unauthorized user, such as a hacker. -
Asymmetric encryption
This type of encryption uses a public and a private key that are mathematically linked. While the private key is kept secret by the data owners, the public key is shared among authorized users.
What are the key differences between data masking and encryption?
Both data masking and encryption conceal sensitive information and enable organizations to comply with data privacy standards such as HIPAA, PCI DSS, and CPRA. The main difference between them is functionality.
Masked data remains usable for development and QA teams in production and testing environments, while encrypted data is challenging to work with.
Another difference is the ability to recover original data values. Masked data cannot be reversed, while encrypted data can be decrypted with the right key.
The table below sums up how the two compare.
| Features | Data masking | Data encryption |
| How it works | Replaces sensitive values with realistic, fictitious ones | Converts plaintext into cipher-text with an algorithm and a key |
| Reversible | No, for static and in-flight masking | Yes, with the right key |
| Data usability | Stays usable for dev, testing, analytics, and AI | Unusable until it's decrypted |
| Best for | Non-production environments and data sharing | Data at rest and in transit |
| Main risk | Weak masking that breaks referential integrity | Key theft or poor key management |
When should you use data masking?
Data masking is a persistent data security solution, meaning it secures data at rest, and in motion. It’s particularly useful for securing PII that has consistent formatting, like credit card, drivers license, or Social Security numbers, while ensuring that the data remains functional.
Following data masking best practices, teams commonly mask:
-
Credit or debit cards
-
Bank accounts
-
Social Security Numbers
-
Medical records
-
Personally Identifiable Information (PII)
- Test data for dev and QA environments
- Data used to train or ground AI models
When should you use data encryption?
Data encryption secures data by rendering it unreadable, unless it is decrypted with an encryption key. Advanced encryption methods are nearly impossible to break, but this level of security often reduces the data’s functionality.
Given its drawbacks, encryption is most helpful for securing unstructured data at rest, or data that is being transferred between networks. It is ideal for securing PII found within:
- Files
- Videos
- Images
Data tokenization, which can be reversed, is an alternative method for protecting sensitive data. Data tokenization involves substituting sensitive data with a non-sensitive equivalent or “token” for use in databases or internal systems. Like data masking, tokenized data remains functional and usable for development and testing. In most data tokenization software systems, the original data is stored securely in an external, centralized data vault outside of the local IT environment.
How K2view masks, encrypts, and tokenizes sensitive data
With K2view, you don't have to pick between masking and encryption. K2view Data Masking is a standalone solution that's quick and easy to implement, thanks to AI. It uses entity-based data masking technology that includes masking, encryption, and data tokenization tools, so data stays secure, at rest or in motion.
K2view features:
1. Standalone solution
Teams can deploy data masking on its own, then add test data management or synthetic data generation later if and when they need them.
2. Quick and easy to implement, thanks to AI
K2skills and K2assistant, K2view's AI-powered implementation tools, automate setup. Time-to-value is quick, training is minimal, and non-technical users can configure masking.
3. Business entity approach
K2view organizes data by business entity, such as a customer, payment, order, or device. Masked data keeps its referential integrity and semantic consistency across every system.
4. In-flight data masking
Data is masked as it moves to the target environment, so PII is never exposed at rest.
5. Dozens of customizable masking functions
Out-of-the-box functions make implementation fast, and they stay flexible as requirements change.
6. Integration with any source
Structured and unstructured data, including images, PDFs, and text files, is masked across every source. Coverage is complete, compliance holds, and the deployment is future-proof.
7. Built-in encryption
Each business entity's data is stored in its own Micro-Database™, encrypted with a 256-bit key. That eliminates the risk of a mass breach.
8. Decentralized tokenization
Each entity's sensitive data is tokenized inside its own Micro-Database, so there's no central vault for attackers to target. Learn more about data tokenization solutions.
9. Foundation for test data management and synthetic data generation
The same platform carries into later phases, so the initial investment delivers more over time.
Conclusion
Data masking vs encryption comes down to what you need to do with the data. Masking replaces sensitive values for good, so teams can use the data safely outside production. Encryption keeps data unreadable at rest and in transit, and anyone with the key can restore it. Most enterprises need both, plus tokenization for reversible use cases like payments.
K2view puts all three on one platform, organized by business entity.
Learn how K2view data masking tools
support data masking AND encryption.


